Agentic AI Screening for Portfolio Investment: Replicate, Audit, Extend
Should an LLM agent team choose the investable universe before a precision-matrix optimiser weights it, and does the paper's Sharpe advantage survive honest selection, a longer post-cutoff window and real news coverage?
Headline result
Rebuilt the paper’s LLM agent screen and precision-matrix optimiser on free S&P 500 data, then scored a pre-registered extension once. Over Jan 2015 to Dec 2023 the agent team earned a Sharpe of 0.18 against 0.51 for the unscreened book (p = 0.049). On the paper’s own window the headline cell reached 0.69, not the paper’s 1.09.
Figures
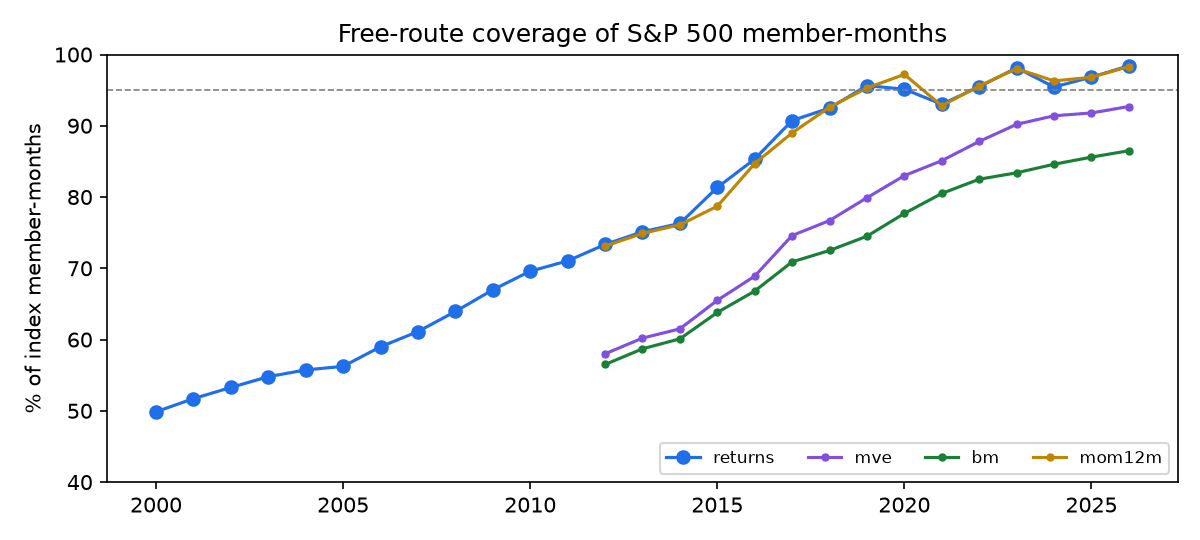
Return coverage rises from about 50% in 2000 to 92–98% from 2018, so the early years carry survivorship bias. 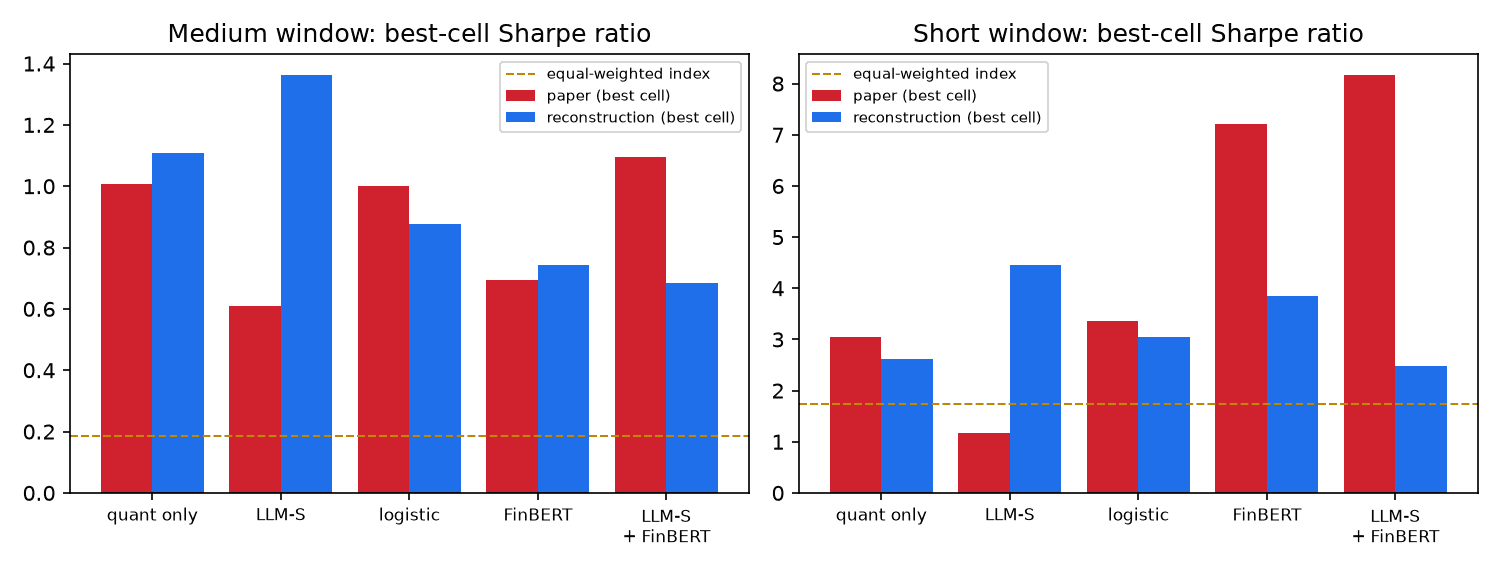
The unscreened book reproduces (Sharpe 1.11 against the paper’s 1.01), but the paper’s headline LLM screen with FinBERT falls from 1.09 to 0.69. 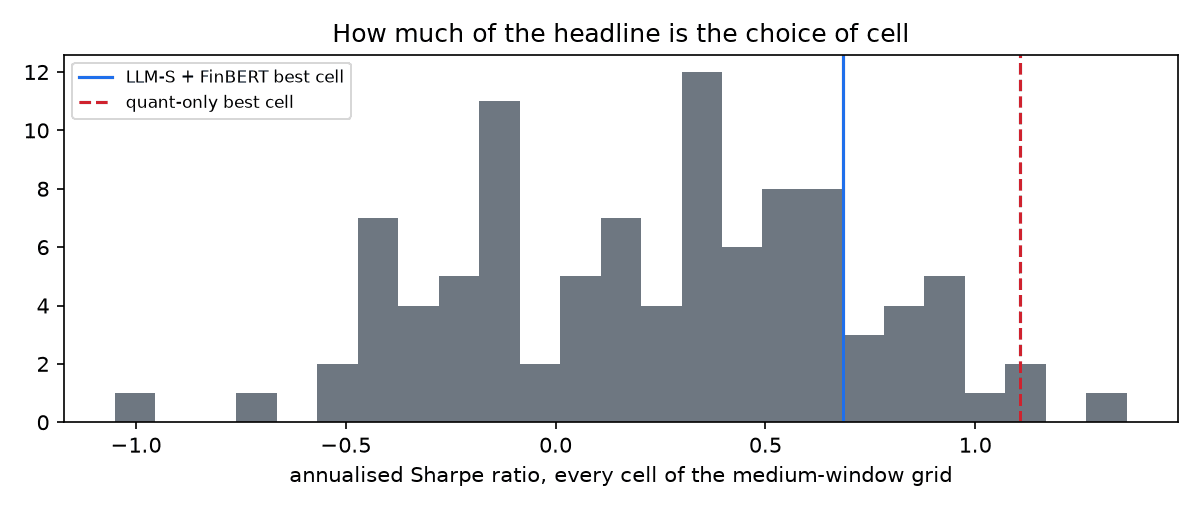
The headline result (0.69) sits inside a wide spread across 99 tested configurations, below the best quant-only one (1.11); deflated Sharpe 0.22. 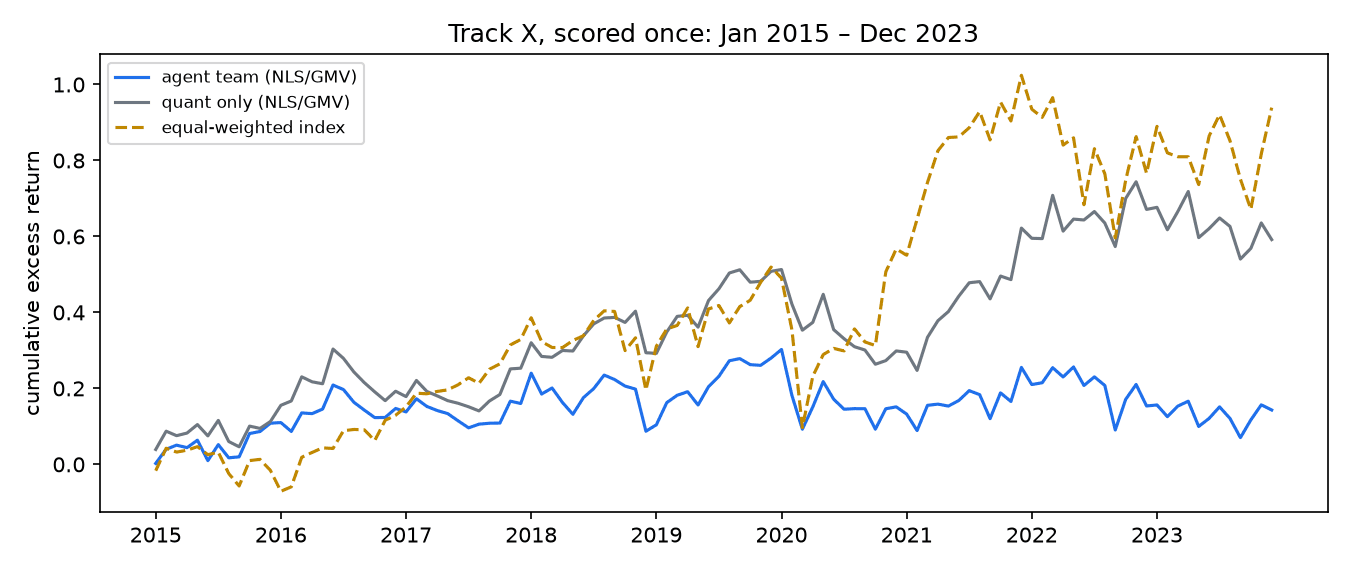
Scored once, the agent team earned a Sharpe of 0.18 against 0.51 for the unscreened quant-only book (p = 0.049).
Data used
- S&P 500 point-in-time membership (fja05680/sp500) and FNSPID daily prices, 1999–2023, topped up with Nasdaq.com closes
- SEC EDGAR XBRL company facts for market value, book-to-market and gross profitability
- S&P 500 news articles (KrossKinetic), 2006–2024, and FNSPID headlines to Dec 2023, scored with FinBERT
Source paper
Caner, Capponi, Sun and Tan (2026), Designing Agentic AI-Based Screening for Portfolio Investment
Sign in to open the full write-up, notebook, tested code and data. Papers to Projects is free with an account; no paid membership needed.